
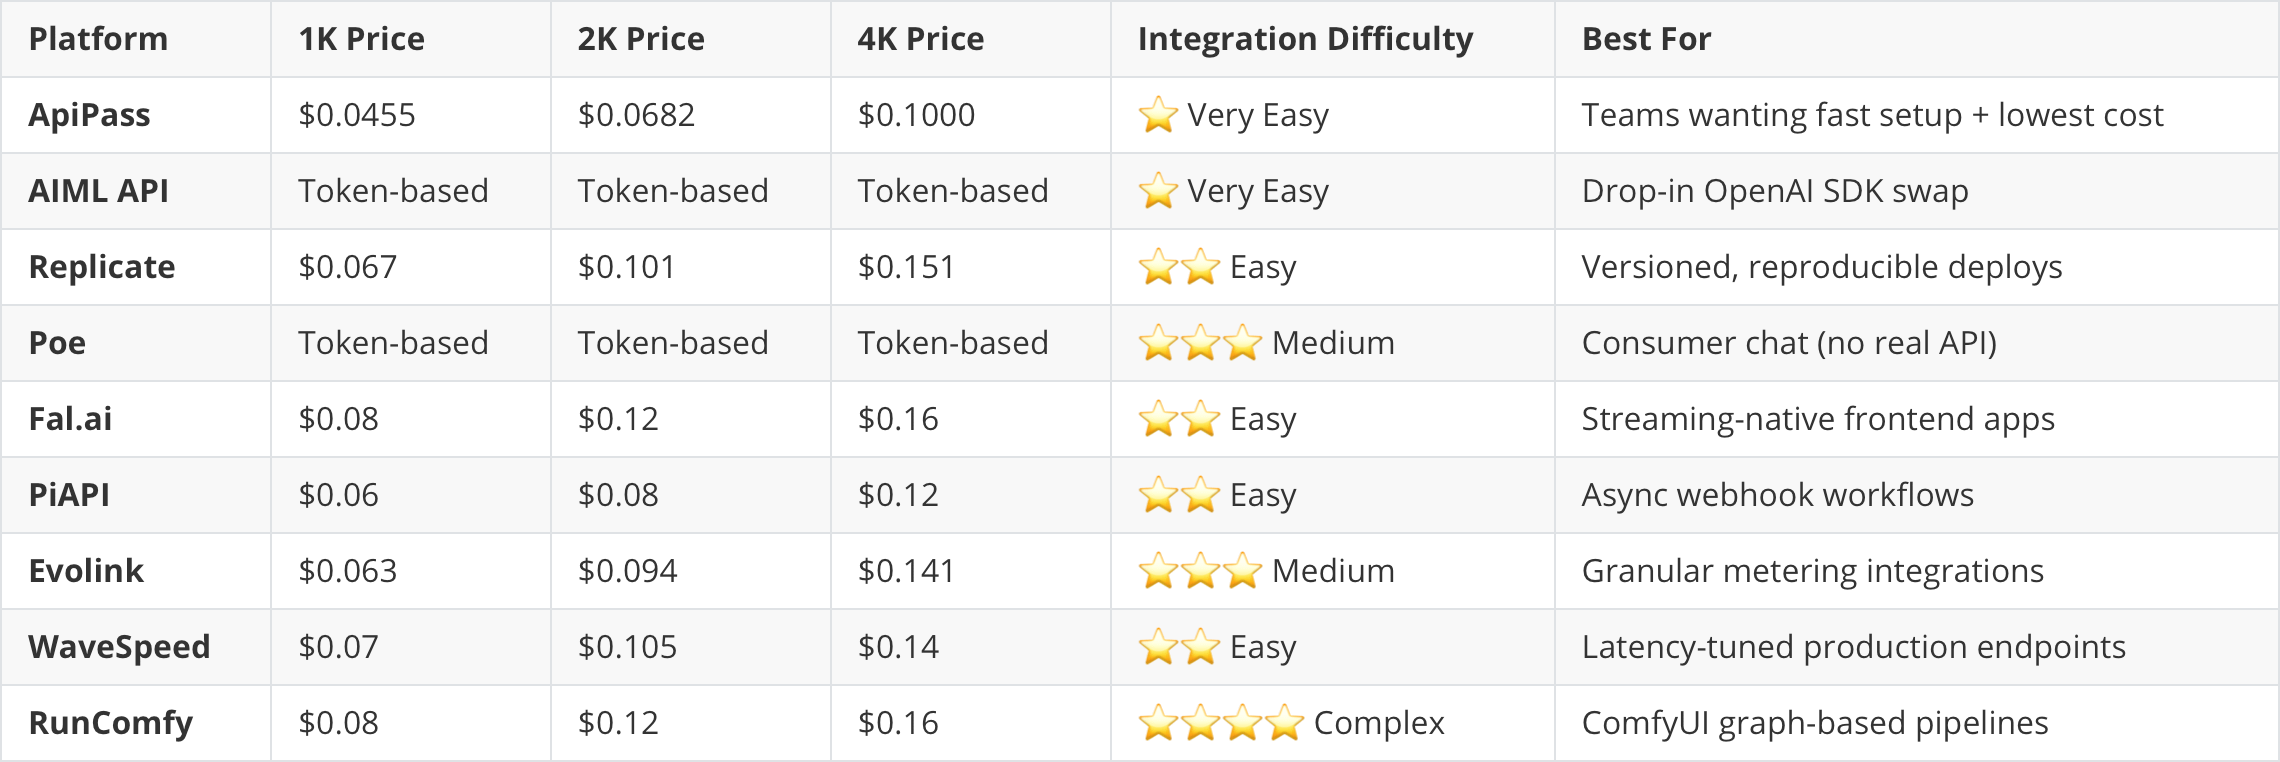
Choosing a Nano Banana API provider isn’t just about price — for engineering teams, integration complexity often determines whether a project ships in a day or drags on for weeks. Authentication flows, SDK quality, async job handling, error semantics, and documentation depth can vary dramatically across providers, even when they’re all serving the same underlying Gemini 3.1 Flash Image model. This guide ranks 9 leading Nano Banana 2 API providers by developer experience and integration difficulty, so you can pick the platform that fits your team’s stack and timeline.
TLTR — Quick Comparison Table
1. ApiPass
Introduction
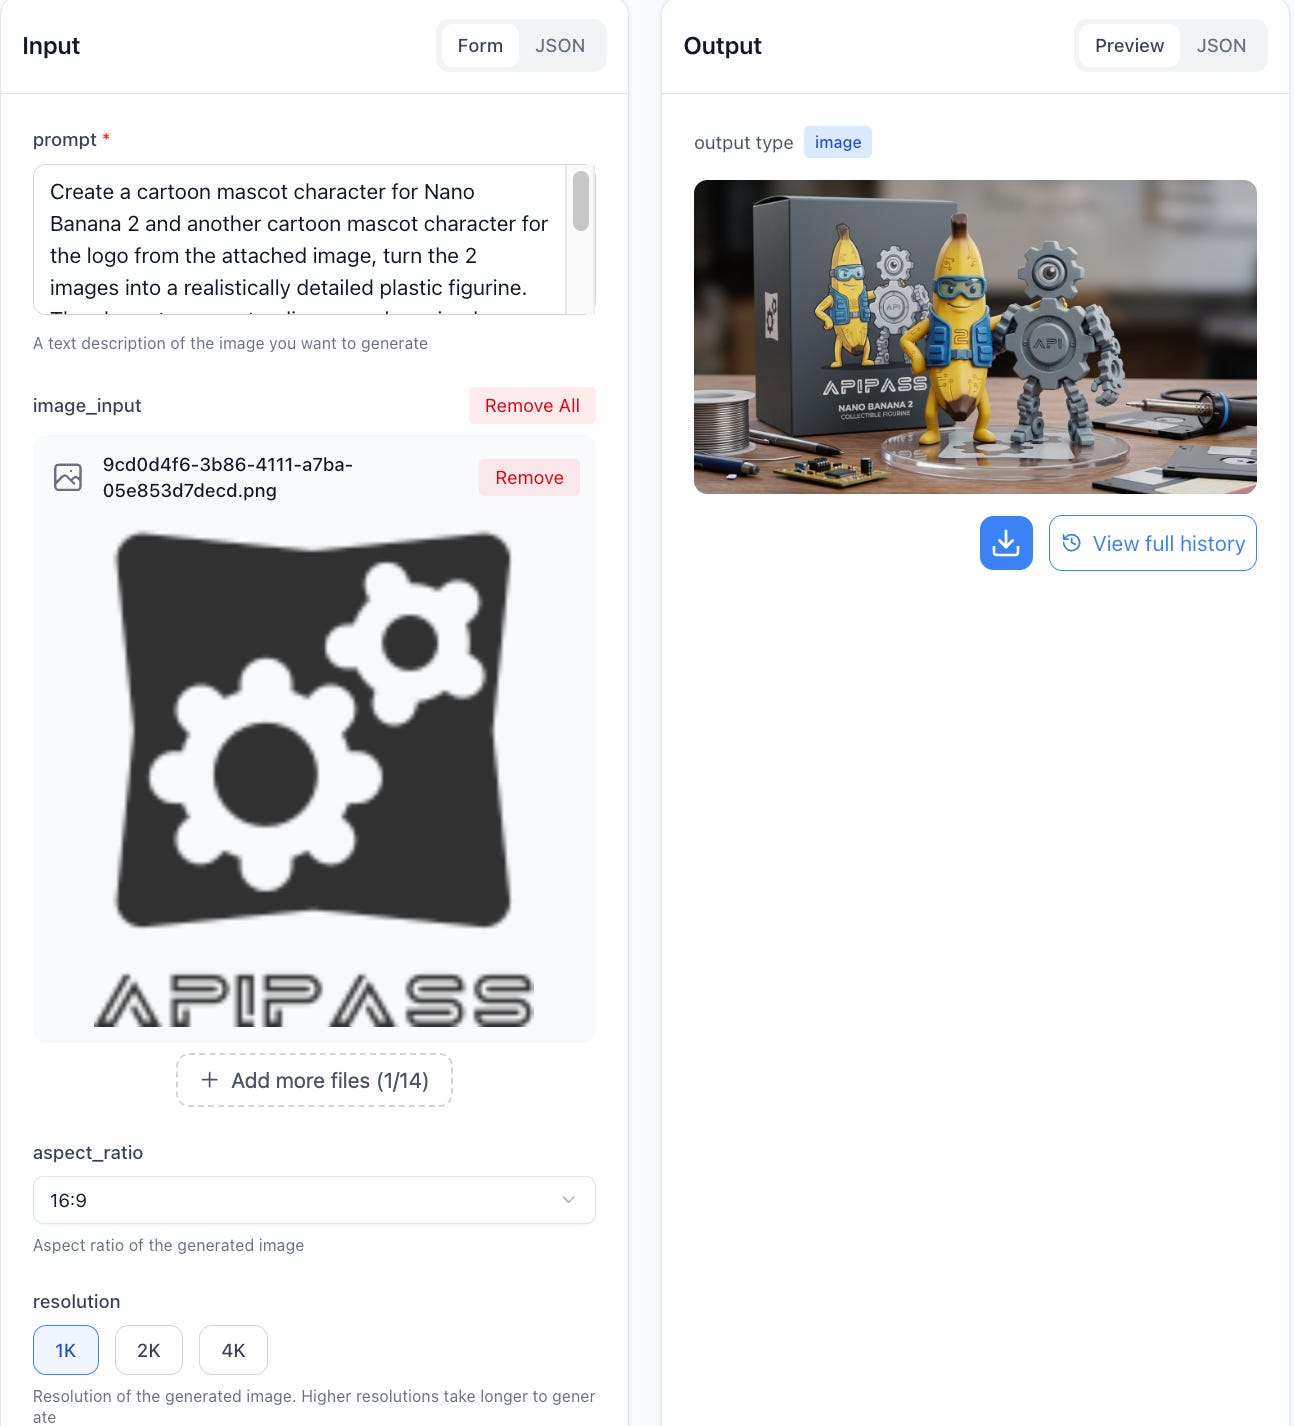
ApiPass offers Nano Banana 2 API through a clean, async job-based REST API designed to minimize integration friction. It uses a standard create-task / query-task pattern with Bearer Token authentication, JSON payloads, and predictable response schemas — making it one of the fastest Nano Banana 2 endpoints to integrate from scratch.
Integration Experience
Authentication: Standard Authorization: Bearer YOUR_API_KEY header — no OAuth flows, no signing.
Two-endpoint design: POST /api/v1/jobs/createTask to submit, GET /api/v1/jobs/recordInfo?taskId=... to poll.
Optional callback URL: Pass callBackUrl in the request body to receive task completion notifications instead of polling.
Clear state machine: Task states are explicitly defined as waiting → queuing → generating → success / fail, eliminating ambiguity in async handling.
Rich input parameters: Supports up to 14 reference images, aspect ratios from 1:1 to 21:9, resolution tiers (1K / 2K / 4K), and toggles for google_search and image_search grounding.
Predictable response shape: Every response returns code, message, and data — with data.resultJson carrying the final image URLs.
24h status monitor: Public uptime dashboard shows ~98% success rate over the last 24 hours, giving teams visibility into platform reliability before committing.
Pros & Cons
Pros:
Minimal boilerplate — a working integration can be built in under 30 minutes with just curl or fetch.
Optional webhook callback removes the need to write polling loops.
Explicit task state values map cleanly onto frontend UI states.
Cheapest 1K pricing in this comparison combined with 35%+ savings vs. OpenAI’s equivalent endpoint.
Same callback structure mirrors the query response — one parser handles both flows.
Cons:
No official typed SDKs (yet) — teams currently integrate via raw HTTP.
Async job pattern requires either polling or webhook setup (no synchronous one-shot endpoint).
Pricing
1K: $0.0455 per image (10 credits)
2K: $0.0682 per image (15 credits)
4K: $0.1000 per image (22 credits)
Best For
Teams that want the fastest possible integration path with the lowest per-image cost, plus production-grade features like webhook callbacks, multi-image fusion (up to 14 refs), and Google Search grounding — all behind a clean two-endpoint REST API.
2. AIML API
Introduction
AIML API is built around one core integration promise: OpenAI SDK compatibility. If your codebase already calls the OpenAI Python or Node SDK, switching to Nano Banana 2 on AIML API often means changing two lines — the base_url and the model parameter.
Integration Experience
OpenAI-compatible request schema: Use the official openai SDK directly, just point it at AIML’s base URL.
Single endpoint pattern: Synchronous request/response — no async polling required for most flows.
Bearer token auth: Standard Authorization header, identical to OpenAI.
Token-based metering: Aligns with how teams already track LLM costs.
Pros & Cons
Pros:
The lowest-friction migration path of any provider for teams already on OpenAI SDKs.
No new SDK to learn — request/response shapes are familiar.
Unified billing across many frontier models reduces vendor sprawl.
Cons:
Token-based pricing makes per-image cost forecasting harder than flat-rate platforms.
Less granular control over generation parameters compared to native Nano Banana 2 endpoints.
Pricing
Input: $0.325 per 1M tokens
Output: $78 per 1M output tokens
Best For
Backend teams already invested in the OpenAI SDK ecosystem who want a near-zero-effort path to adding Nano Banana 2 to existing pipelines.
3. Replicate
Introduction
Replicate is one of the most mature ML-as-an-API platforms in the industry, with first-class SDKs for Python, Node, Go, and Elixir. Its Nano Banana 2 endpoint inherits Replicate’s well-known versioning system, prediction lifecycle model, and best-in-class developer documentation.
Integration Experience
First-class SDKs: replicate.run() is a single function call that handles auth, polling, and result parsing automatically.
Versioned models: Pin to a specific model version hash for reproducible production deploys.
Webhook support: Receive prediction completion events without polling.
Streaming support: Some models support streamed outputs natively.
Excellent documentation: Per-model API examples, schema explorer, and live playground.
Pros & Cons
Pros:
SDK ergonomics are arguably the best in the ecosystem.
Versioning makes rollbacks and A/B tests trivial.
Strong observability — every prediction has a permanent URL with logs and metrics.
Cons:
Slightly higher per-image cost than aggregator platforms.
Per-second GPU billing on some non-Nano-Banana models can complicate cost forecasting.
Pricing
1K: $0.067 per image
2K: $0.101 per image
4K: $0.151 per image
Best For
Engineering teams that prioritize SDK quality, model versioning, and reproducibility — especially those building production systems where rollback safety and observability matter.
4. Poe
Introduction
Poe (by Quora) is fundamentally a consumer chat product, not a developer API platform. While Poe does offer a Server Bot API for building bots that run inside Poe, it does not expose Nano Banana 2 as a direct programmatic endpoint for backend image generation in the way the other providers in this list do.
Integration Experience
No direct REST API for Nano Banana 2 image generation — access is through the Poe chat UI or subscription.
Server Bot API exists but is designed for building Poe bots, not for embedding Nano Banana 2 in third-party apps.
Token-based per-message pricing under the hood, billed via points.
Subscription-required to access most usage tiers.
Pros & Cons
Pros:
Zero technical setup for end-users — pure chat UX.
Single subscription unlocks many frontier models, useful for prompt research and experimentation.
Cons:
Not suitable for production backend integration.
No standard REST/SDK access pattern for Nano Banana 2 generation.
Variable token-based message cost makes precise budgeting difficult.
Pricing
Subscription Tiers (Billed Yearly):
10,000 points/day: $49.99/year (~$4.17/month)
1 million points/month: $199.99/year
2.5 million points/month: $499.99/year
5 million points/month: $999.99/year
Nano-Banana-2 Per-Message Token Rates:
Input: $0.51 / 1M tokens (17 points / 1K tokens)
Output (text): $3.03 / 1M tokens (100 points / 1K tokens)
Output (image): $60.61 / 1M tokens (2,000 points / 1K tokens)
Best For
Individual end users and prompt researchers who want chat-based access to Nano Banana 2 alongside other frontier models — not developers building production applications.
5. Fal.ai
Introduction
Fal.ai is built specifically for real-time, end-user-facing AI applications. Its Nano Banana 2 endpoint emphasizes streaming responses and low cold-start times, with native client SDKs for JavaScript and Python that handle queue management transparently.
Integration Experience
@fal-ai/client SDK for JavaScript/TypeScript with first-class streaming support.
Queue-based async pattern abstracted behind fal.subscribe() — feels synchronous to the developer.
Realtime WebSocket connections for ultra-low-latency interactive experiences.
Browser-safe key proxying built into the SDK for frontend apps.
Standardized input/output schemas across all Fal-hosted models.
Pros & Cons
Pros:
Best-in-class developer experience for frontend / interactive apps.
Streaming UX makes generation feel near-instant to end users.
Browser proxy support eliminates the need to build a backend just to hide API keys.
Cons:
Higher per-image price than aggregators.
Streaming-first design adds slight complexity for pure backend batch workloads.
Pricing
1K: $0.08 per image
2K: $0.12 per image
4K: $0.16 per image
Best For
Frontend and consumer app developers who want a polished SDK with native streaming and browser-safe key handling out of the box.
6. PiAPI
Introduction
PiAPI focuses on async-first workflows with strong webhook support, making it well-suited for backend pipelines that don’t need synchronous responses. It also offers a no-code workspace alongside its REST API for non-technical team members.
Integration Experience
Standard async task pattern: Submit task → receive task_id → poll or wait for webhook.
Webhook-first design: Webhooks are well-documented and reliable, reducing the need for polling logic.
REST API with clear JSON schemas.
Bearer token auth.
Pros & Cons
Pros:
Webhook reliability simplifies long-running batch generation jobs.
No-code workspace accelerates prototyping for non-engineers.
Competitive pricing at all resolution tiers.
Cons:
Smaller ecosystem and fewer community examples than Replicate or Fal.
No first-class typed SDKs — integration is via raw HTTP.
Pricing
1K: $0.06 per image
2K: $0.08 per image
4K: $0.12 per image
Best For
Backend teams building async generation pipelines who want reliable webhooks and a balance between developer-grade API access and no-code tooling.
7. Evolink
Introduction
Evolink takes a credit-based, modality-level metering approach, which trades a small amount of integration complexity for highly granular cost observability. Each modality (input image, output image at each resolution, web search, image search, input tokens, output tokens) is metered separately.
Integration Experience
Credit-based billing system requires understanding of credit-to-USD conversion.
REST API with multi-modality request schema — more parameters to configure than flat-rate platforms.
Detailed line-item cost reporting in API responses.
Bearer token auth.
Pros & Cons
Pros:
Most granular cost observability in this comparison — every modality is a separate line item.
Cheap reference image input ($0.0005) makes multi-reference workflows affordable.
Excellent for finance/ops teams that need precise cost attribution.
Cons:
Steeper learning curve than flat per-image platforms.
Estimating total cost upfront requires understanding which modalities each request will trigger.
Pricing
Input Image (Reference): $0.0005 per image
Output Image 0.5K: $0.042 per image
Output Image 1K: $0.063 per image
Output Image 2K: $0.094 per image
Output Image 4K: $0.141 per image
Web Search: $0.013 per request
Image Search: $0.013 per request
Input Text: $0.0005 / 1K tokens
Output Text + Thinking: $0.0028 / 1K tokens
Best For
Teams that need surgical cost observability across mixed-modality workloads and are willing to invest a bit more upfront integration effort for long-term cost transparency.
8. WaveSpeed
Introduction
WaveSpeed positions itself as a latency-optimized inference platform with a clean, flat per-image pricing structure. Its Nano Banana 2 endpoint is tuned for fast cold-starts and consistent throughput.
Integration Experience
Standard REST API with synchronous and async modes.
Clean, predictable JSON schemas.
Bearer token auth.
Optional add-ons (web search, image search) toggleable via request parameters.
Four resolution tiers including a 0.5K option for previews and lightweight use cases.
Pros & Cons
Pros:
Pricing math is trivial — no token conversions or credit calculations.
Latency-optimized infrastructure suits real-time and high-frequency workloads.
0.5K tier is great for cheap preview generation.
Cons:
1K base price slightly higher than aggregator platforms.
Smaller community and fewer third-party tutorials than Replicate or Fal.
Pricing
0.5K: $0.045 per image
1K: $0.07 per image
2K: $0.105 per image
4K: $0.14 per image
Web Search add-on: +$0.014 per request
Image Search add-on: +$0.014 per request
Best For
Latency-sensitive production endpoints that need predictable per-image pricing and consistent throughput without the complexity of token-based metering.
9. RunComfy
Introduction
RunComfy is built around ComfyUI — the popular node-based visual workflow editor. Its Nano Banana 2 integration is designed to plug into custom multi-step graphs, which makes it powerful for visual designers but the most complex integration option for teams that just want a simple API call.
Integration Experience
Two parallel pricing models: per-image API and GPU-based plans — adds up-front decision complexity.
ComfyUI workflow design required to take full advantage of the platform.
Serverless API export: Visual workflows can be turned into API endpoints with one click.
GPU-based plans require understanding VRAM requirements and machine selection.
Custom node ecosystem offers flexibility but adds learning curve.
Pros & Cons
Pros:
Unmatched flexibility for multi-step visual pipelines.
One-click serverless API export turns ComfyUI graphs into production endpoints.
Pro plan offers strong value ($10 monthly credit + 20%+ GPU discount) for heavy users.
Cons:
Highest integration complexity in this comparison — requires understanding ComfyUI before productive use.
Two-tier pricing model (per-image API + GPU plans) can confuse first-time users.
4K per-image price ($0.16) is the highest tier in this comparison.
Pricing
Per-Image API (Nano Banana 2):
Standard (1K): $0.08 per image
0.5K: ~$0.06 (0.75× standard rate)
2K: ~$0.12 (1.5× standard rate)
4K: ~$0.16 (2× standard rate)
Web Search add-on: +$0.015 per request
Platform Plans:
Pay as You Go: Standard GPU rates, no subscription required.
Pro: $19.99/month (regularly $29.99), billed annually at $239.90 with 4 months free, plus 20%+ discount on all GPU rates and $10 monthly credit.
Best For
ComfyUI power users and visual workflow designers who want to embed Nano Banana 2 inside complex multi-model graphs — and are willing to accept a steeper learning curve in exchange for maximum flexibility.
Final Thoughts
Integration complexity often matters more than per-image cost when you’re under deadline. A platform that’s $0.01 cheaper per image but takes two extra weeks to integrate rarely wins on total project cost.
Here’s a quick decision framework based on integration difficulty and developer experience:
Fastest setup + lowest cost → ApiPass
Drop-in OpenAI SDK swap → AIML API
Versioned, reproducible deploys → Replicate
Streaming-native frontend apps → Fal.ai
Async webhook backend pipelines → PiAPI
Granular cost observability → Evolink
Latency-tuned production endpoints → WaveSpeed
Visual ComfyUI workflows → RunComfy
Consumer chat (no real API) → Poe
If your team values minimal time-to-first-image-generated, ApiPass and AIML API are the clearest winners — both can go from API key to working integration in well under an hour. For teams with more specialized needs (streaming, versioning, granular metering, or visual workflows), the right pick depends entirely on which tradeoffs align with your stack.